Header Adder Field Guide: When Four Modes, Five Separators, and Three Output Formats Decide Whether Your CSV Lands as Typed Records or as Anonymous Numeric Columns

Header Adder field guide poster

Most CSV pipelines die at the first row. A database export arrives as four anonymous numeric columns, an API response lands without a header line, or a third-party data dump lists fields as Column 1, Column 2, Column 3 and forces the consumer to guess the schema. The fix is a single-purpose tool that adds the missing header row – and the decisions you make while using it decide whether the downstream parser treats your data as typed records or as one long string of confusion. The Header Adder does exactly this: it reads headerless CSV and emits header-bearing CSV (or JSON, or HTML table), with five header modes, five separators, three output formats, and one preview-only toggle that turns the whole tool into a header-generation auditing lab.

When the Header Row Goes Missing

Three everyday situations land a CSV on your desk without a header line. Database exports from legacy systems (Oracle, SQL Server, and Access, in particular) often emit the data rows without their column names when the query was crafted against a SELECT * shortcut or a view without column metadata. API responses occasionally return raw arrays of arrays, not arrays of objects, and the consumer is left to label them. Numeric datasets – benchmark scores, measurement logs, or simulation output – arrive as a flat matrix where every column has meaning but none has a name.

The mistake most people make is to type the headers in manually. That works for two columns. It does not work for thirty. And it does not survive schema drift: when the source adds or removes a column, your hand-written headers silently go wrong.

The Five Header Modes and What Each Produces

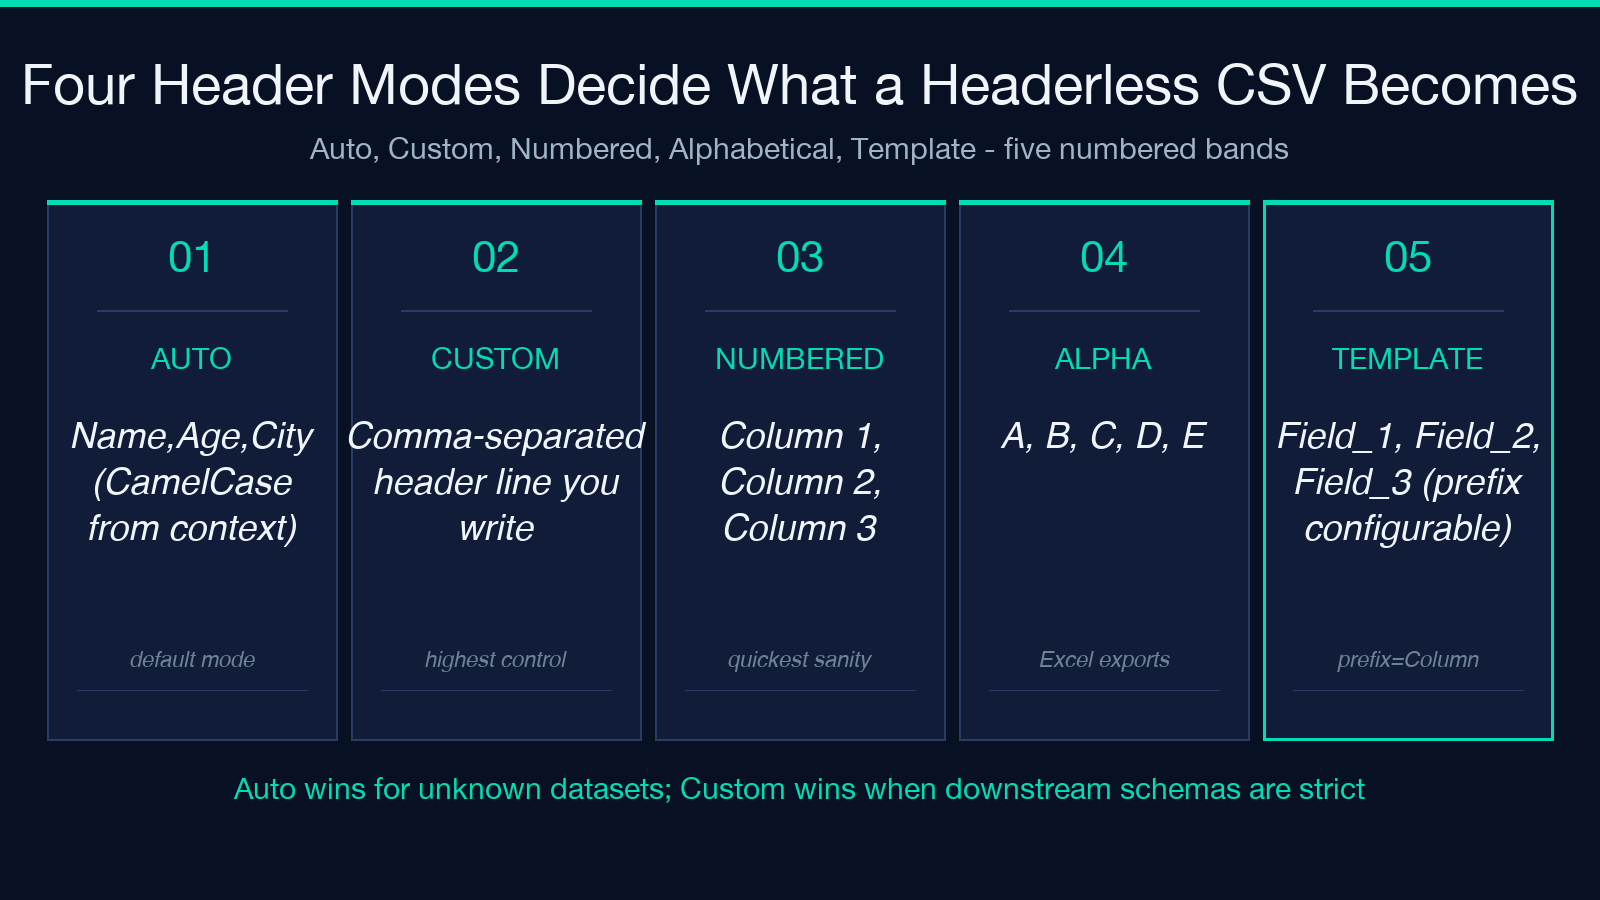
Header Mode is the most important decision in the tool. It decides what the first row of your output becomes, and it has five choices, each tuned for a different downstream consumer.
Five header modes numbered list

Auto-Generate is the default. The tool analyzes the data rows and infers the most likely column names – Name, Age, City, Position for a database export of employees; date, value, unit for a measurement log. It uses a CamelCase naming convention and reads the first data row to disambiguate columns that look numeric. It is the mode to reach for when you genuinely do not know the schema.

Custom lets you supply your own header line. You paste Name, Age, City, Position into the Custom Headers field and the tool emits those exact strings as row zero. This is the mode to reach for when the downstream consumer has a defined schema and your input is just missing the labels.

Numbered produces Column 1, Column 2, Column 3 and so on. Useful for quick sanity checks and for cases where the column name does not matter but the column index does. Excel and most CSV viewers treat this as the universal fallback.

Alphabetical produces A, B, C, D, E. It looks terse in the spreadsheet but it is also the only mode that does not require the consumer to know any internal naming convention. Use it when you are handing the file to a non-technical stakeholder.

Template produces Field_1, Field_2, Field_3 with a configurable prefix (default: Column). Use it when you need the headers to look like placeholder schema names that downstream tooling can rename via sed or find/replace.

The Five Separators Decide How Columns Split

Comma is the default, but the tool accepts five separators. Semicolon is the second-most-common – particularly in European exports where the comma is the decimal separator. Tab is the third, used by Excel on Windows when the file is saved as .txt and by Unix tooling that wants to avoid quoting entirely. Space and pipe are the rare-but-not-zero options, mostly seen in academic corpora and in some log formats. Choose the separator that matches your source file; the tool defaults to comma but the choice matters because a misaligned separator will silently collapse the entire row into one column.

The Three Output Formats and the Preview-Only Toggle

CSV is the default output, with a header row on top and the original data rows below, separated by your chosen separator. TABLE emits an HTML
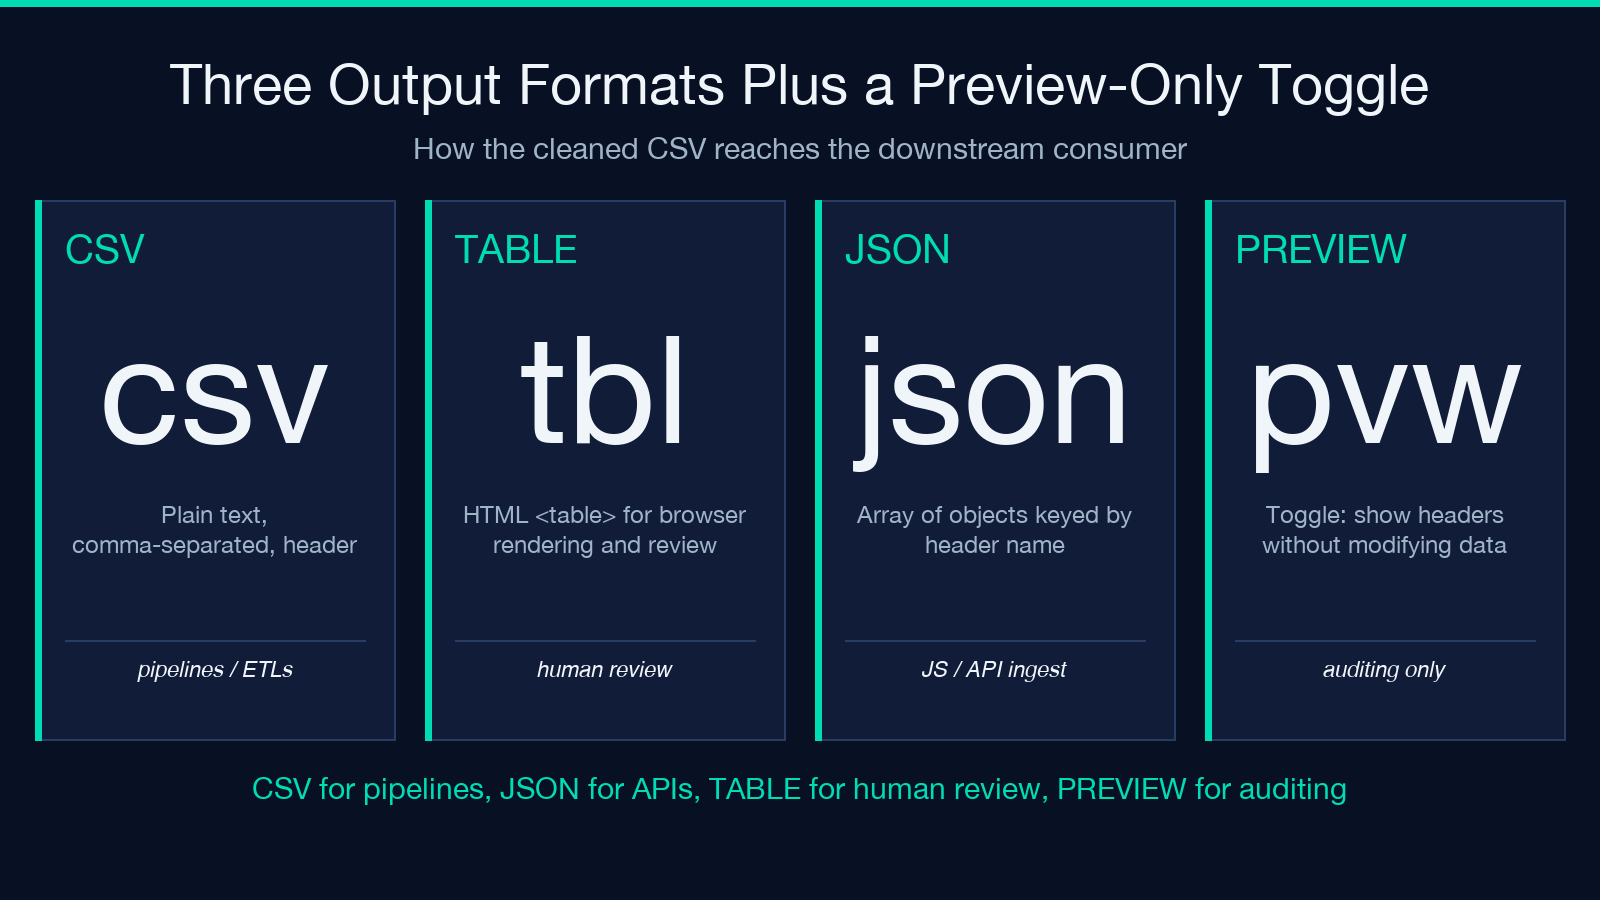
for browser rendering - use it when you need to review the result in a UI without first opening it in a spreadsheet. JSON emits an array of objects keyed by the header name - use it when the downstream consumer is JavaScript or a JSON-typed API ingest path. The Preview-Only toggle turns the whole tool into a header-generation auditing lab: paste your data, choose your header mode, and the tool returns only the generated header row without modifying the data.

Three output formats plus preview-only toggle

The Five Decisions That Decide Whether the Header Row Actually Helps

Decision one: do you know the schema? If yes, use Custom with the exact column names. If no, use Auto. Decision two: is the separator comma or semicolon? Pick the wrong one and the entire file collapses. Decision three: will the downstream consumer accept CSV, JSON, or HTML table? Pick the format that requires the least conversion. Decision four: is the header row canonical (will you reuse it across multiple files) or one-off? Canonical headers belong in Custom; one-off headers can be Auto. Decision five: do you need to audit the header generation without committing to it? Then toggle Preview-Only on and inspect the result before applying it to a real file.

A Worked Example on a Headerless Database Export

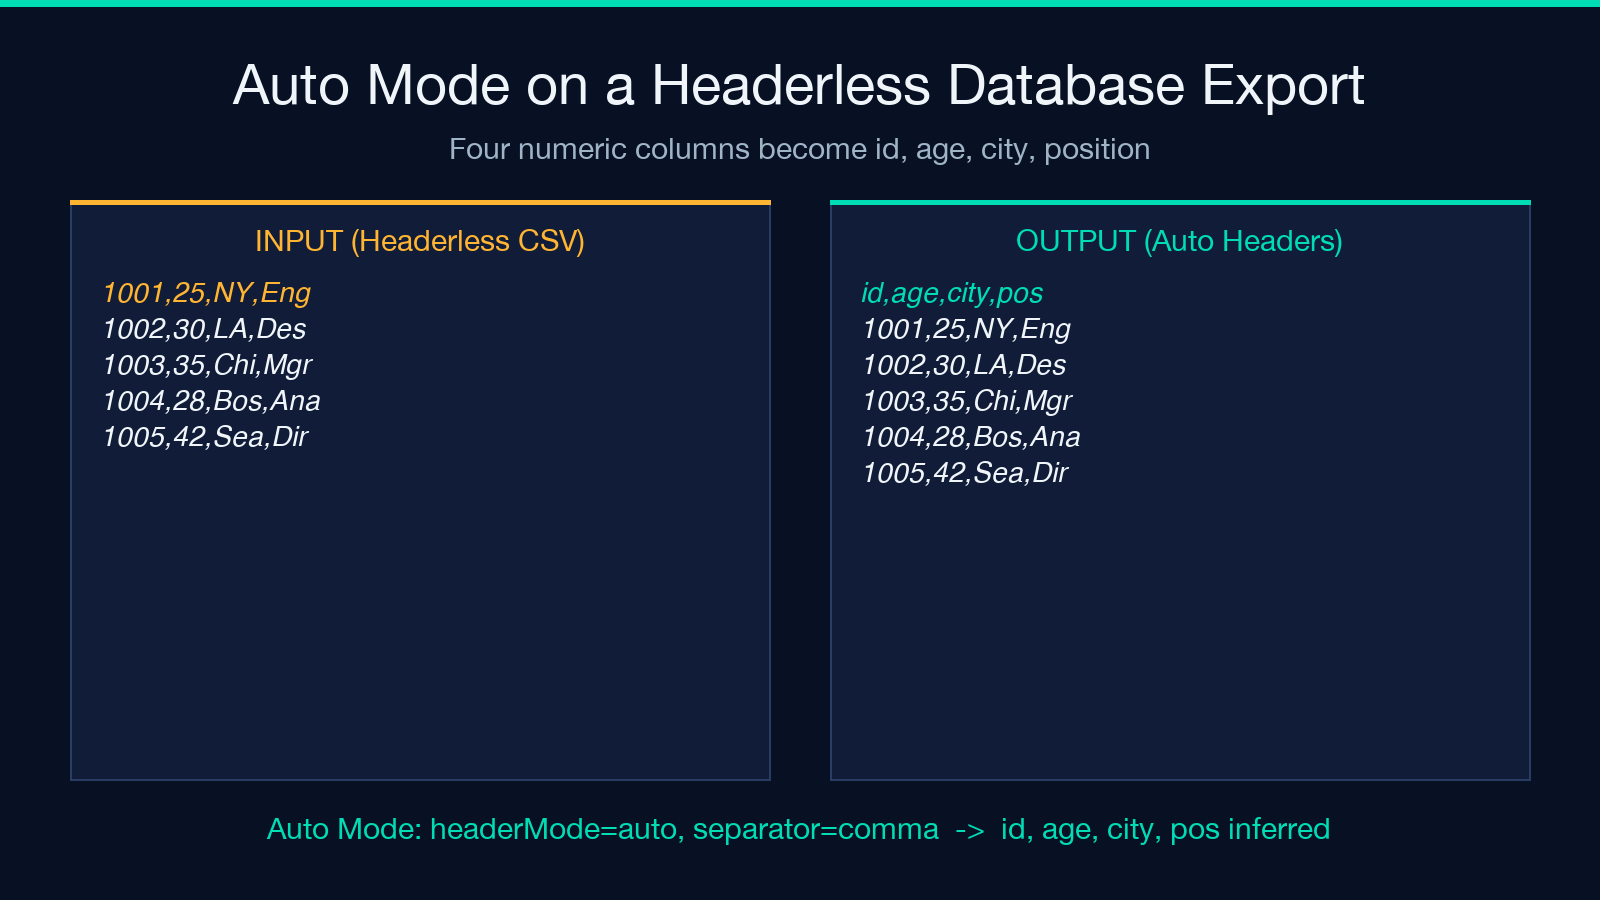
Suppose your export reads 1001,25,New York,Engineer with three more rows of id, age, city, position data and no header line. With Header Mode set to Auto and Separator set to comma, the tool emits the same five rows prefixed by id, age, city, position - exactly the schema the downstream parser needed. Try the same input with Header Mode set to Numbered and the output becomes Column 1, Column 2, Column 3, Column 4 with the same data rows below. Both are valid; which one you pick depends on whether the consumer cares about the column names or the column positions.

Auto mode worked example on headerless CSV

When Auto Gets It Wrong

Auto-Generate is the most convenient mode, but it has three known failure cases. When two columns have similar types and similar value ranges (say, two numeric columns), the tool sometimes swaps their inferred names. When the first data row is itself a header-like string (a date column header, a unit-suffixed column name), the tool can mistake it for metadata. And when the file has fewer than five data rows, the inference has too little signal and may produce generic names like Field 1, Field 2. The fix for all three is to switch to Custom with the correct schema - or to use a longer input file so Auto has more rows to learn from.

Header Mode + Output Format: The Two-Axis Decision Matrix

The two header decisions that interact most are Header Mode and Output Format. Numbered + CSV is the universal fallback: any spreadsheet can read it. Custom + JSON is the most production-friendly: the downstream JavaScript consumer gets typed objects keyed by the exact schema names. Auto + TABLE is the most useful for human review: the generated header names are visible in the browser without any file conversion. Template + CSV is the most useful for migration paths: the Field_1, Field_2, Field_3 placeholder names can be renamed via sed or find-and-replace once the consumer's canonical schema is known.

For more tooling on CSV structure, see the Header Remover (the inverse operation), the CSV Malformed Row Surgeon (for repairing rows that arrive with broken quoting or mixed delimiters), and the broader Data Processing tools collection for header detection, BOM cleanup, and quote normalization.

The header row is the schema. When it is missing, every downstream consumer has to guess, and guessing is where data pipelines silently lose rows. The Header Adder is the smallest possible fix for that problem: one decision (Header Mode), one structural choice (Separator), one output format (CSV / JSON / TABLE), and a preview-only toggle for safety. Run the input through it once, audit the generated header row, and the rest of the pipeline can read the file as if the schema had always been there.

Comments

No comments yet. Why don’t you start the discussion?

    Leave a Reply

    Your email address will not be published. Required fields are marked *