PDF AcroForm Filler: The Five Decisions That Decide Whether Your Filled Form Is Real
You have a stack of 200 onboarding PDFs. Each one has the same six form fields. Your job is to fill them all with names, employee IDs, and start dates from a CSV, then deliver a clean, flattened, non-editable PDF back to HR.
If you try to script that with a generic PDF library, three of the 200 come back looking right, two come back with the wrong checkbox state, one comes back with the dropdown still showing its default, and one comes back with the field text rendered in a font that no longer exists in the PDF. The other 193 throw silent warnings that you only spot when HR opens them in Adobe and calls you.
Form filling is not “find the field name and write a string into it.” It is a small protocol with five load-bearing decisions, and the cost of skipping any one of them shows up downstream, in a different tool, in a different hand, at a different time.
The engine decision is the one you cannot undo
The first decision is which library writes into the AcroForm. There are three reasonable choices on a Node server, and they make different promises:
pdf-libreads AcroForm dictionaries, writes the field values, and rewrites the PDF. It does not touch XFA. It does not auto-flatten. It does exactly what you ask, which means it does not save you from yourself.pdf-libplus a hand-written XFA-stripping pass handles hybrid PDFs by removing the XFA packet and falling back to the AcroForm dictionary. This is the right path for forms that look modern and behave old.- A pure XFA form, the kind Adobe LiveCycle used to produce, is not writable by
pdf-libat all. You can fill the visible AcroForm fallback, or you can convert the PDF to a true AcroForm upstream, but you cannot fill a pure XFA form with the same code path you use for everything else.
Most of the time, your form is a regular AcroForm and pdf-lib is the right choice. The decision matters because if you commit to a wrapper that promises XFA support, you will pay a complexity tax for the 95 percent of forms that never had XFA in the first place.
The key naming decision decides whether your JSON survives contact with the PDF
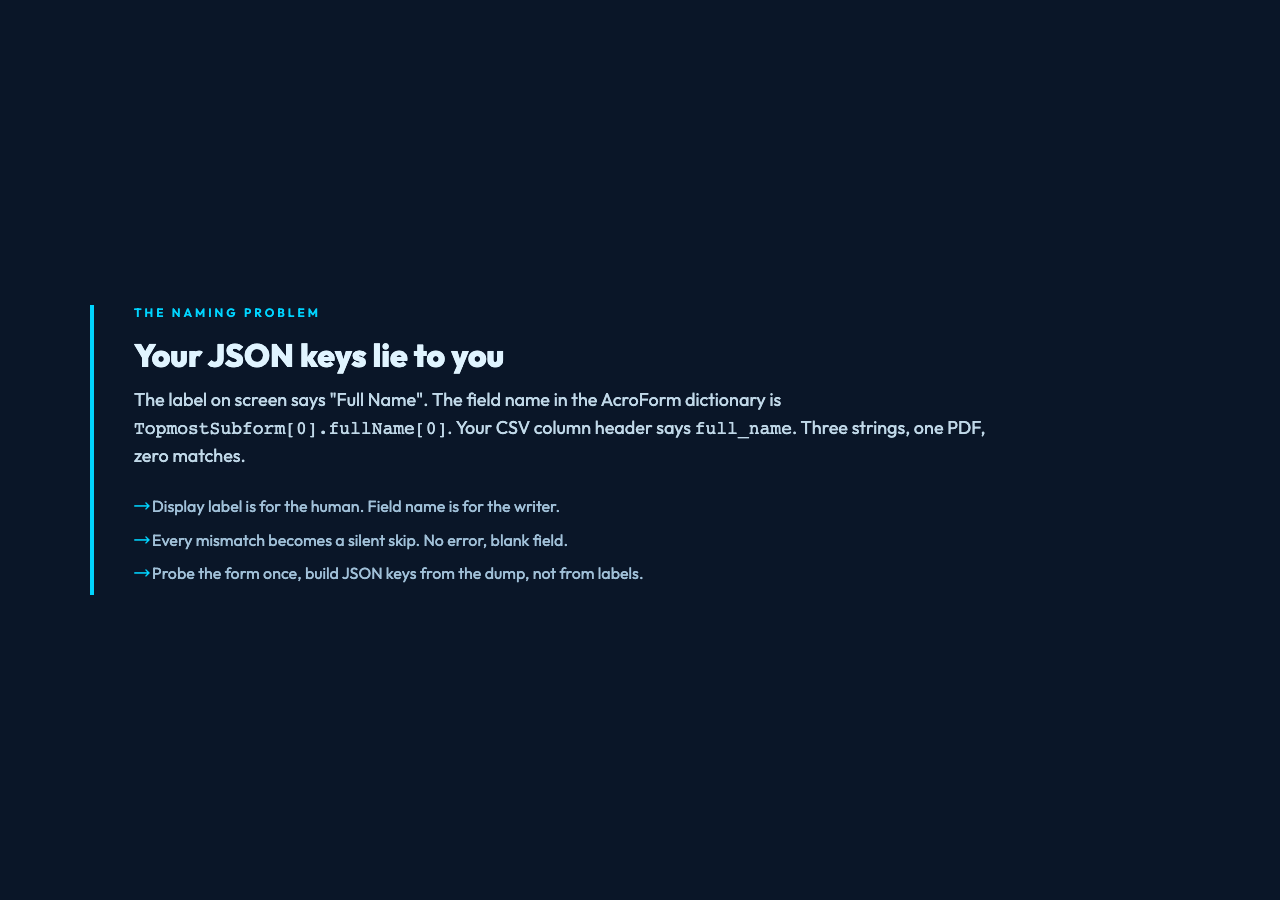
AcroForm fields are addressed by their fully qualified name, not their display label. The label is what the user sees, the name is what you write to. They are almost the same string. They are not the same string.
A form called “Full Name” on screen might be form.fullName, form.full_name, TopmostSubform[0].fullName[0], or body.p1.fullName depending on the authoring tool. The JSON you build from your CSV is going to use the labels your spreadsheet column header said. Every field name mismatch becomes a silent skip: the field is unchanged, no error is raised, and the filled PDF looks correct until someone opens it in Adobe Reader and notices the field is still blank.
The fix is to dump the actual field names once. Open the form in a small probe, list every name, and build your JSON keys from the dump, not from the labels. The PDF AcroForm Filler exposes a strict mode that fails the entire batch the moment a single field cannot be mapped, which converts these silent skips into loud, fixable errors.
The value-type decision is where checkboxes, radios, and dropdowns fail
Text fields are forgiving. You write a string, the field stores it, the PDF renders it. The other three field types are not forgiving, and each has its own wire format:
- Checkboxes in AcroForm take a value, not a boolean. The value is the field’s “on” name, which is usually
Yesbut is sometimesOn,1, or the name of the field itself. Writingtruedoes nothing. Writingfalsedoes nothing. You write the on-name string and the field flips to its checked appearance. - Radio groups take one string from a defined set, exactly matching one of the option export values. The string is not the label, it is the export value the authoring tool wrote. If your CSV has
United Statesand the radio expectsUS, the radio silently stays on its default. - Dropdowns and list boxes take a single string (dropdown) or an array of strings (list) from the same export-value vocabulary. Passing
["Reading", "Music"]to a field whose export values areread,music,artwrites nothing and falls back to the first entry.
A clean approach is to normalize your data before the write pass: convert booleans to the field’s on-name, convert labels to export values through a small lookup, and convert arrays to the field’s expected list shape. The 200-PDF batch becomes a 200-iteration loop over the same normalized JSON object.
The flatten decision decides who can edit the result
Flattening means converting the AcroForm fields into plain page content. After flattening, the recipient cannot click into the form fields and change them. The fields are gone.
Two cases want flattening: legal documents that need to be signed and archived as static PDFs, and onboarding forms that get routed to multiple reviewers who should not be able to edit the data. Two cases want to keep the form alive: a draft that will go through review and revision, and a template that needs to be filled many times from different data sources.
If you flatten by default, your reviewer cannot add notes. If you never flatten, your legal team has to manually lock the PDF before sending. The PDF AcroForm Filler exposes a flatten option that is one line, but the decision is a workflow decision, not a tool decision.
The strict-mode decision decides whether errors are loud or silent
Every AcroForm filler has the same default behavior: write what you can, skip what you cannot, return success. This is the polite behavior for an interactive tool and the wrong behavior for a batch job.
Strict mode flips the contract. If any field cannot be mapped, if any value is not in the option set, if any required field is empty, the entire fill aborts and the original PDF is returned unchanged. The batch is atomic. Either all 200 are filled correctly, or none of them are. You can fix the data, re-run, and trust the output.
Without strict mode, your batch job returns 200 PDFs, 198 of which are correct, 2 of which are not, and you do not find out until the human opens the file.
The pipeline that earns its keep
A reliable form-filling pipeline has six steps:
- Probe the PDF once to extract the actual field names and their option export values.
- Build a small schema mapping your CSV columns to the PDF field names.
- Normalize each row through the schema before the write pass.
- Fill with
pdf-liband the XFA-stripping pass for hybrid forms. - Run in strict mode and abort on the first mapping failure.
- Flatten the final output if the document is going to an external recipient.
The whole pipeline runs in a few hundred milliseconds per form. The 200-PDF batch that used to take a day of human work and a stack of “fix this one” emails takes a single script run, and the result is reproducible.
If you want to see the AcroForm Filler in action, you can open the tool, drop in a real PDF, and feed it a JSON object to see exactly which fields your naming choice would have written and which ones it would have silently skipped. Most of the surprises in form filling show up in the first probe. The PDF AcroForm Filler makes the probe a one-line operation.
Fill your forms once, with names that match, values that exist, and a strict mode that catches what your data did not.