If you have ever flipped a coin ten times and tried to count how often the streak lands on exactly three heads, you have already been working with the binomial distribution. The math behind it is one of the cleanest objects in probability, and yet the practical question of which probability to compute is where most people get stuck.
The Binomial Distribution Calculator resolves that confusion by accepting three inputs (trials, successes, success probability) and returning four probabilities at once: P(X = k), P(X ≤ k), P(X ≥ k), and the cumulative distribution plus the moments. You do not have to pre-decide which tail you need. The tool figures out the mode from the inputs you give it.
What the binomial distribution actually models
The distribution applies whenever you have a fixed number of independent trials, each one ending in success or failure, with the same probability of success on every trial. The classic examples are coin flips, dice rolls under a threshold, manufactured items passing inspection, or users clicking an advertisement. The distribution is parameterized by two numbers: n (the number of trials) and p (the probability that any single trial succeeds).
What the distribution gives you is the full probability that you observe exactly k successes. From there, three derived quantities cover almost every practical question. P(X = k) answers questions like “what is the chance that exactly 3 of 10 coin flips come up heads.” P(X ≤ k) answers “what is the chance of three or fewer heads.” P(X ≥ k) answers the mirror question, “at least three heads.” The two cumulative quantities together always sum to 1 plus P(X = k), because k itself is counted in both tails.
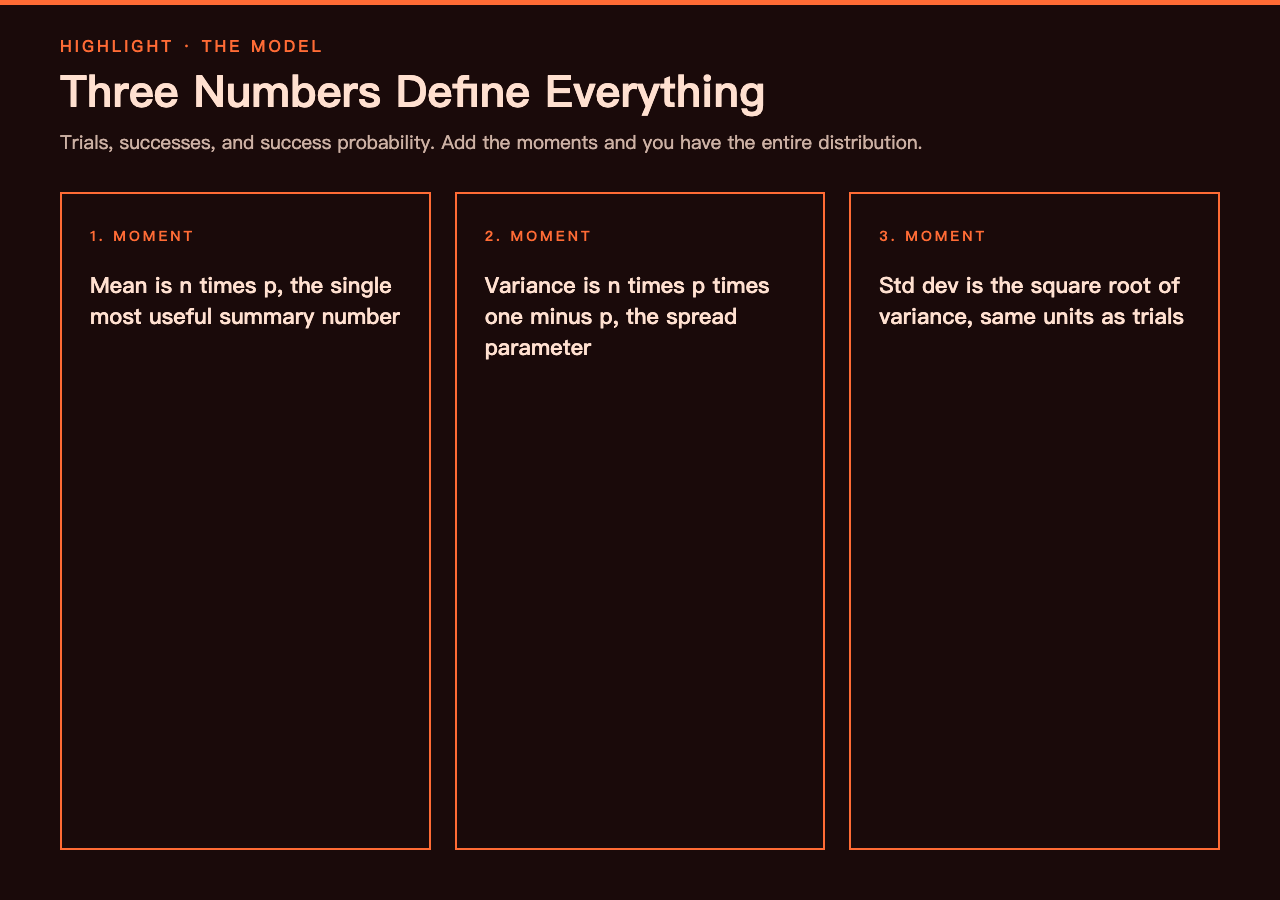
The distribution also has clean moment formulas. The mean is np, the variance is np(1-p), and the standard deviation is the square root of the variance. These three numbers describe where the distribution is centered and how spread out it is, which is why the calculator returns them along with the probabilities. They give you a sanity check: if you are computing a probability of 0.5 but the mean is 5 and you are looking at k = 50 in 100 trials, something has gone wrong with the inputs.
The three probability modes and when to use each
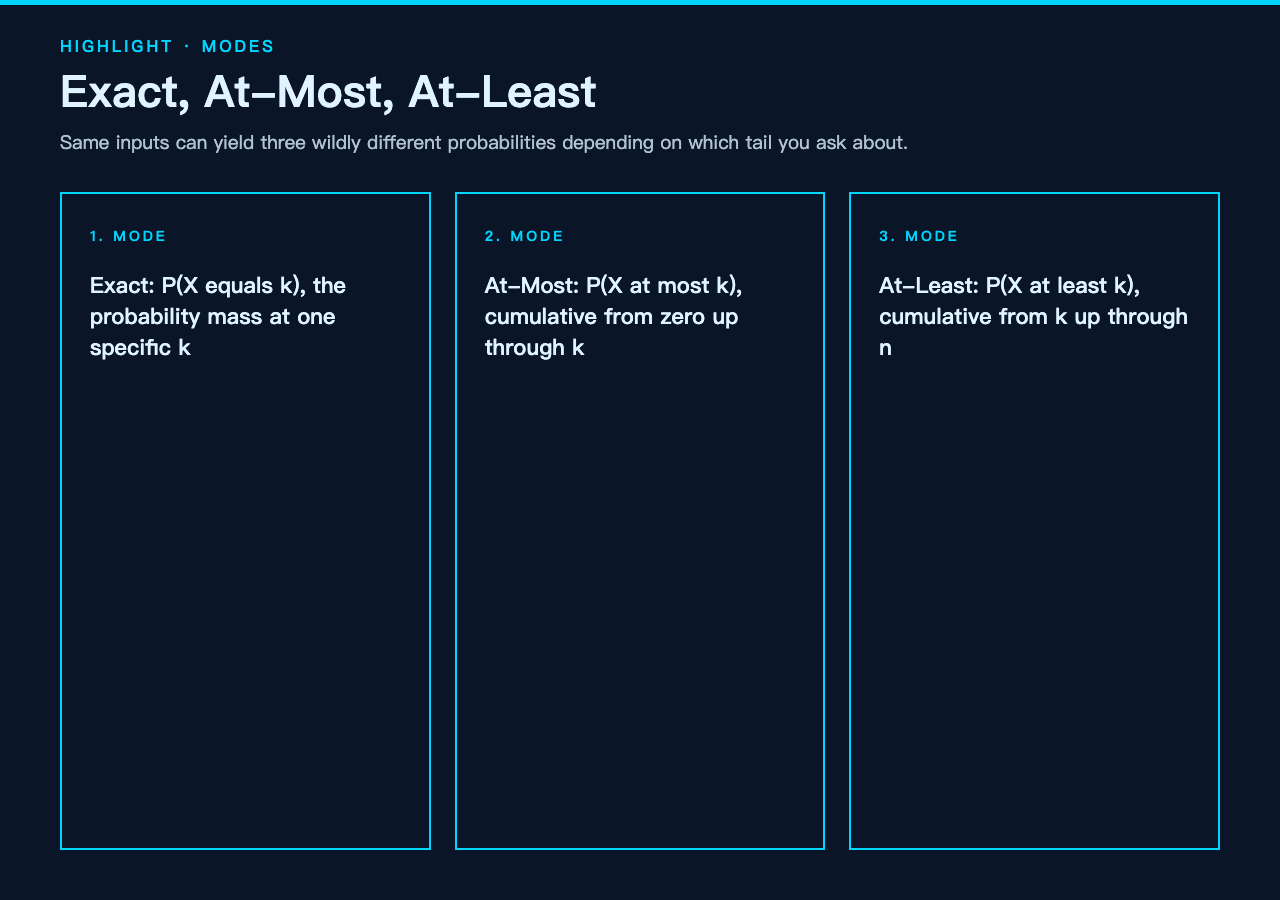
The tool exposes three probability modes via a select input: exact, at-most, and at-least. Each one corresponds to a different cumulative question, and choosing the right one matters because the returned numbers differ by orders of magnitude in some regions.
Exact mode returns P(X = k), the probability that you observe exactly the target number of successes. This is the most common mode for textbook exercises and for situations where you need the probability of a specific outcome, like drawing a particular number of red balls from an urn. The shape of this probability across k is the binomial probability mass function, and it peaks near the mean np.
At-most mode returns P(X ≤ k), the cumulative probability from zero up to and including the target. This is the mode you want for hypothesis testing with an upper-tail alternative, for inventory calculations where you want to know the chance of staying under a threshold, or for quality control questions like “what is the probability that at most 2 of 50 parts are defective.”
At-least mode returns P(X ≥ k), the cumulative probability from the target up to n. This is the mirror of at-most and applies to questions like “what is the probability that at least 8 of 10 respondents answer yes.” It is also the mode you want for power calculations when you are designing an experiment and need to know how often you will observe a result at least as extreme as a threshold.
For symmetric inputs (trials = 2k, successProbability = 50 percent, successes = k), the at-most and at-least probabilities are equal by symmetry, and both are roughly half. For asymmetric inputs, they diverge, and the calculator handles the divergence without any manual conversion.
How the calculator handles percent and proportion inputs
One small but important detail is the inputScale option. You can enter success probability as either a percentage (0 to 100) or a proportion (0 to 1). The choice affects only how you write the number; the underlying calculation is identical. If you forget which one you picked and start typing a value that is out of range for the other scale, the tool will not silently misbehave; the validation layer rejects values outside the declared range.
This matters because it is a common bug in homemade spreadsheets to mix percent and proportion and get answers that are off by a factor of 100. The calculator’s strict separation of the two scales prevents that class of error entirely. If your downstream code expects proportions and you typed 50, the calculator interprets it as 0.5 in percent mode, which is nonsensical; in proportion mode, 50 is rejected as out of range. Either way, you cannot get a silently wrong answer.
The decimalPlaces option lets you tune the output precision from 0 to 10 digits. The default of 4 is appropriate for most reporting use cases. If you are feeding the result into further numerical computation, increase the precision to avoid accumulating rounding error.
Working example: manufacturing defect rate
Suppose a factory produces widgets with a 2 percent defect rate, and you sample 200 widgets at the end of a shift. You want to know the probability that you will see at most 3 defective widgets in the sample, because exceeding that threshold triggers a re-inspection of the entire batch. The inputs to the calculator are trials = 200, successes = 3, successProbability = 2, inputScale = percent, probabilityMode = at-most.
The mean is 4 defects (np = 200 0.02), and the standard deviation is just under 2 (square root of 200 0.02 0.98). The probability of at most 3 defects is the cumulative probability up to k = 3, which is roughly 0.35. That means about a third of batches will trigger a re-inspection under this rule, which is much higher than most production managers expect when they first set the threshold.
If instead you asked the at-least question (at least 8 defects out of 200), the probability drops to roughly 0.025, which is a much more reasonable alert threshold. The same data, two different policy questions, two completely different numerical answers. The calculator’s mode selector is what makes the difference.
Why the exact-cumulative-atleast distinction matters in practice
A frequent source of confusion is that P(X = k), P(X ≤ k), and P(X ≥ k) can differ by orders of magnitude for the same input. For trials = 20, successes = 10, successProbability = 50, P(X = 10) is about 0.176, P(X ≤ 10) is about 0.588, and P(X ≥ 10) is about 0.588 as well (by symmetry, the two cumulative probabilities are equal when k = n/2 and p = 0.5).
But for trials = 20, successes = 5, successProbability = 50, the three quantities diverge sharply. P(X = 5) is 0.015, P(X ≤ 5) is 0.020, and P(X ≥ 5) is 0.994. The exact probability is small because the mean is 10, not 5. The at-most probability is also small because 5 is in the left tail. But the at-least probability is near 1 because 5 is below the mean and most of the probability mass is above it.
This is why the calculator exposes three modes rather than just returning all three at once. The choice of mode communicates intent: when you are asking “what is the chance of at most 5 heads,” you are asking a left-tail question, and the answer is shaped by what counts as “at most” versus “at least” versus “exactly.” Picking the wrong mode gives you a number, but it is the answer to a different question.
When the binomial approximation kicks in
For large n, the binomial distribution converges to a normal distribution with mean np and variance np(1-p). This is the central limit theorem in action. The rule of thumb is that the approximation is good when np ≥ 5 and n*(1-p) ≥ 5. When those conditions hold, you can swap the binomial calculator for a normal-distribution approximation and the answers will agree to three or four decimal places.
For small n or extreme p (very close to 0 or 1), the binomial distribution is highly skewed and the normal approximation breaks down. The calculator works in both regimes because it computes the binomial probabilities directly, without invoking any asymptotic approximation. For trials = 10000, the calculator handles the computation without overflow, which is a non-trivial implementation detail given that the binomial coefficients for n = 10000 are numbers with thousands of digits.
Validation, sanity checks, and the role of moments
Every result from the calculator includes the mean, variance, and standard deviation. These are not just decoration; they are the fastest way to catch an input error. If you accidentally type 50 (fifty percent) when you meant 0.5 (point-five percent), the mean will shift by a factor of 100 and you will see immediately that something is wrong.
The relationship between the moments and the probabilities is also useful for sanity checking. The sum of P(X = k) over all k from 0 to n is 1. P(X ≤ k) + P(X ≥ k) = 1 + P(X = k). These two identities are easy to verify on the calculator’s output and they catch arithmetic errors in downstream pipelines that copy values around.
For more complex workflows, where you need to compute several probabilities in sequence (for example, scanning across a range of k values to plot the probability mass function), the calculator’s JSON output format is well-suited to scripting. You can issue a batch of requests with different (trials, successes, successProbability) tuples and assemble the resulting probabilities into a chart or a table without writing any probability math by hand.
Where the binomial distribution breaks down
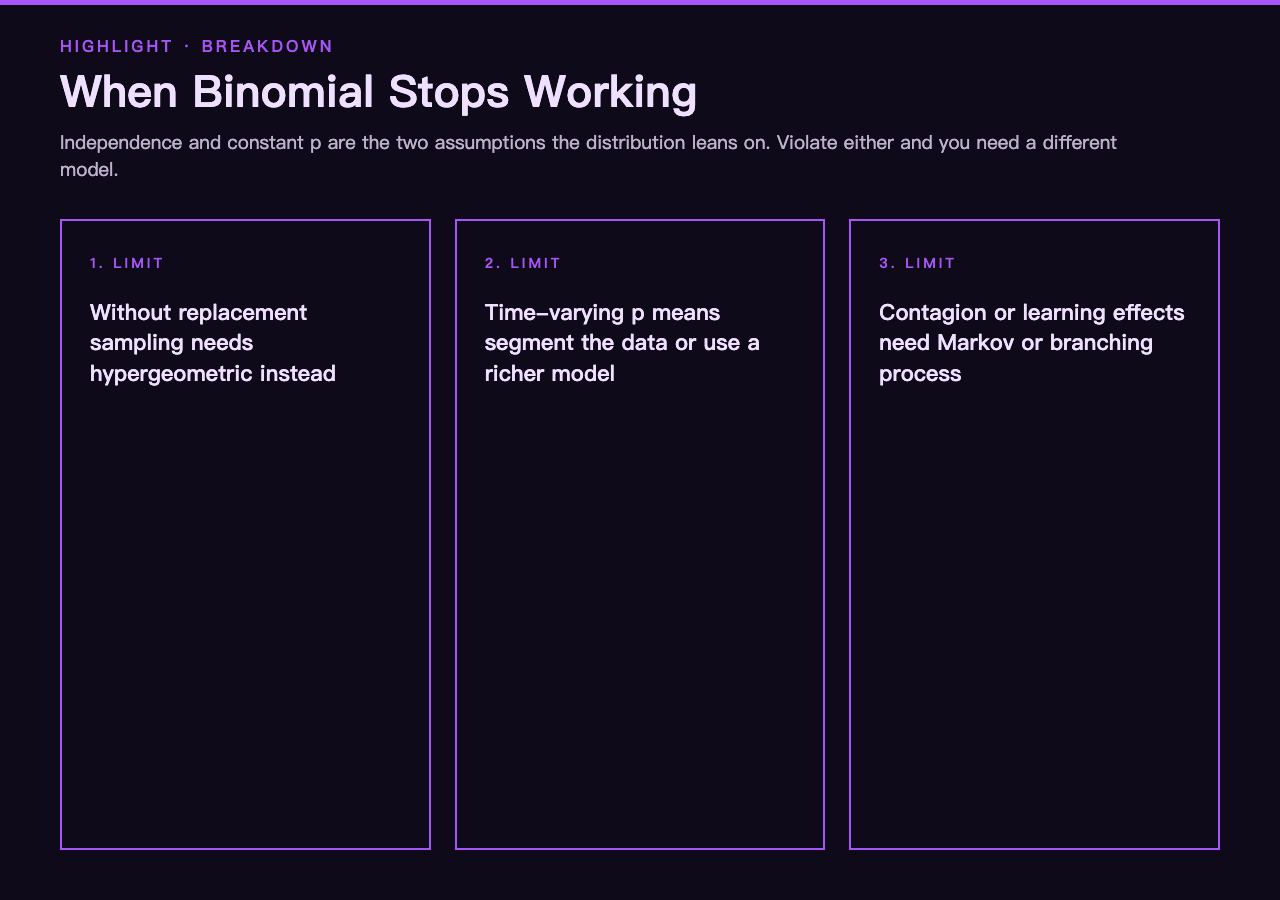
The binomial distribution assumes independence of trials. If your trials are correlated (the first outcome influences the second), the binomial probabilities are no longer correct. Common cases of correlation include without-replacement sampling from a finite population (use the hypergeometric distribution instead), time-series events where each event’s probability depends on the previous state (use a Markov chain model), and contagion processes where exposure increases the probability of further exposure (use a branching process or epidemic model).
The distribution also assumes that the success probability p is constant across all trials. If p drifts (because of a process change, a learning effect, or fatigue), the binomial probabilities are still valid locally for any short window where p is stable, but they are not valid for the long run. In those cases, segment the data and compute binomial probabilities for each segment separately, or use a more complex model that allows p to vary.
For most practical use cases (coin flips, dice rolls, defect rates, click-through rates, conversion rates, survey responses with stable underlying probabilities), the binomial model fits well, and the calculator gives you accurate probabilities in milliseconds. It is a workhorse tool for any kind of binary-outcome experiment.
Explore more probability and statistics tools at elysiatools.com.